701, Chandak Chambers, Andheri Kurla Road, Mumbai 400093
Posts

Category: AI Visibility

Abstract paired metadata tiles demonstrate a wrong-shaped inset slipping through a loose gate and being caught by a fitted gate.
Jul 30, 2026

Testing an Audit Rule Against Known Good and Bad Fixtures

A green audit result is useful only if the rule can reject the defect it claims to detect. Test the rule on paired fixtures: one valid input and one defective input that differs in a single declared property. Freeze the expected classifications before running the rule, then count missed defects separately from valid inputs incorrectly rejected. A passing pair demonstrates a narrow distinction, not that a website is ready for every agent.
Conceptual illustration of repeated product-page tiles filling one sample while another includes variant selection, listing outcomes and a cart with a closed stock gate.
Jul 30, 2026

How to Sample a Large Website for Agent Task Testing

Sample tasks in distinct states, not just URLs. Start with page template, workflow complexity and inventory state, then reserve a task execution for every known combination whose outcome could differ. Use random URL selection for a different question, such as estimating a defined population measure under a suitable statistical design. A small random draw is not a substitute for deliberate coverage of a rare, consequential state.

Conceptual baskets behind separate consent, login and fading-session barriers show why one cart request can require different responses.
Jul 30, 2026

Why an Agent Audit Needs a State Inventory

An agent audit should include every state that changes the correct response to the chosen task, the data that may be returned, or the side effects that are allowed. A successful check from a logged-in account with a populated cart cannot establish what should happen before consent, after logout, with an empty cart, or after a session expires. The task is the unit of work. The state inventory defines the conditions under which that work is judged.

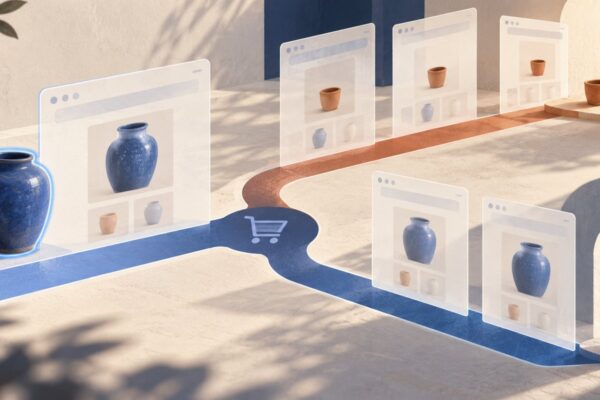
Concept illustration of a selected large pot becoming a small pot at a cart junction while the surrounding page panes remain intact; a second route preserves the large pot.
Jul 30, 2026

Defining the Unit of Analysis in an AgenticReadiness Audit

Use the end-to-end task as the primary unit when an AgenticReadiness audit must establish whether a purchase can be completed correctly. Use page states to locate presentation gaps and tool contracts to locate input, output and state-change defects. Those units answer different questions. Averaging them into one pass rate can hide the boundary where the intended purchase changes.

Conceptual document trays distinguish retained evidence, proposed work and missing records; a split ruler represents an invalid comparison.
Jul 30, 2026

What an Annual ScaleGrowth Research Review Should Measure

An annual research review should show which decisions became better supported, which findings remain comparable, and where the evidence still runs out. A list of published articles or a rising dashboard line cannot answer those questions. The useful unit is a research question linked to a method, retained observations and a bounded conclusion.

Conceptual evidence dossier with two abstract books, source sheets and an empty tray representing a missing execution record.
Jul 29, 2026

Building a ScaleGrowth Capability Dossier From Public Evidence

A ScaleGrowth capability dossier should connect each claim to a dated record and state what that record establishes. Books can establish authorship and published methods. Service pages can describe an offer. Neither is a substitute for a demonstration with a checked result. The useful output is a claim-level proof packet, not a collection of endorsements.

Concept illustration of one open book leading to three incomplete paper forms representing an investigation, an interview and a technical explanation.
Jul 29, 2026

Choosing Between a Research Feature, Founder Interview and Technical Byline

Choose the format by the claim the evidence can sustain. A research feature explains a finding and how it was established. A founder interview examines decisions through answers that have actually been obtained. A technical byline teaches a method with enough detail to assess or apply it. A document can be useful in all three without being sufficient for any external pitch.

Concept illustration of two abstract pages with a shared masthead, different source and sponsor markings, and an unopened terms envelope.
Jul 29, 2026

How to Assess a PR Placement Beyond the Publisher’s Logo

A worthwhile public relations (PR) placement puts a defensible story on a relevant page under terms that match the purpose of the work. A publisher’s logo cannot establish who will write that page, whether it will be advertising, how readers will find it or what the buyer can reuse. Choose only after those questions have page-level answers. Hold the decision when a missing term could change the value.

Concept illustration of release capsules and report sheets: an older equivalent interrupts a priority display, while an incomplete record remains unresolved. Fictional evidence, not company history.
Jul 29, 2026

What Would Establish a First-to-Build Claim for an Audit System?

A first-to-build claim needs more than an early announcement. It needs a defined category, a dated working implementation and a comparison with alternatives that existed at the relevant time. An early record can establish that a system existed by a date. Only the comparison can establish whether that date precedes other qualifying systems, within the market actually examined.

Conceptual illustration of a query aimed at one storage bin while a selection glow marks a different bin, representing a wrong-warehouse lookup. Not a test screenshot.
Jul 29, 2026

Publishing Negative Results From an Agent Readiness Test

A failed readiness test becomes useful when another person can reconstruct the expected task, reproduce the wrong result and see what evidence would change the conclusion. The record below reports a real local execution of a deliberately faulty lookup against fictional stock data. It demonstrates a testing method, not a defect discovered in a live business or a measurement of agent performance.

1 … 4 5 6 7 8 … 33
✉ Free Growth Audit
☎ Call Now Get Free Audit →